Google Unveils R4T Diffusion Model: A Breakthrough in Scalable, Low-Latency AI Search and Retrieval
MOUNTAIN VIEW, Calif. — In a significant development for artificial intelligence search infrastructure, Google has officially introduced a groundbreaking framework designed to optimize query fan-out operations. Dubbed the Retrieve-for-Train-Diffusion (R4T) Model, the system successfully addresses one of the most stubborn computational bottlenecks in modern AI architecture: high inference latency paired with exorbitant processing costs.
By marrying reinforcement learning (RL), synthetic data generation, and a compact generative neural network, Google researchers have engineered a system capable of delivering production-ready, expert-level search capabilities at a fraction of the traditional resource expenditure. According to the company’s technical disclosures, the framework slashes latency from nearly 50 seconds down to a fraction of a second, opening the door for massive scalability across search engines, recommendation systems, and generative AI platforms.
Main Facts
The R4T Diffusion Model represents a radical shift in how search engines execute "query fan-outs"—the process of expanding a single user query into multiple distinct, complementary search directions or sub-queries to gather comprehensive results.
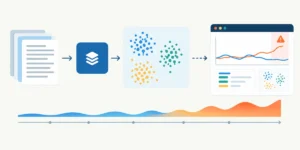
- The Architecture: R4T is a three-stage framework powered by a remarkably small 53.9-million-parameter diffusion model. It combines reinforcement learning training, synthetic data generation, and neural-network knowledge distillation.
- Performance Gains: The model achieves a 12x to 20x speedup over traditional autoregressive approaches. While autoregressive fan-outs can drag on for up to 50 seconds under large context batches, R4T operates within sub-second to low-second windows.
- Core Optimization Pillars: The system is explicitly trained to balance three competing search objectives: diversity (avoiding redundant synonyms), coverage, and complementarity (capturing useful, distinct aspects of the original query).
- Beyond Search: While optimized for retrieval tasks, the R4T framework’s underlying principles are scalable to recommender systems (such as YouTube and Google Discover), planning tasks, and creative content generation.
Chronology of Development and Deployment
The path from academic research to public disclosure spans nearly a year, highlighting a methodical approach to stress-testing and safety evaluation.
March 2026: The Initial Research Paper
The foundational concepts behind the R4T framework were first detailed in an academic paper published in March 2026. Researchers outlined how separating reward-driven discovery from inference-time deployment could solve the massive computational overhead associated with high-order property retrieval. During this early phase, testing was primarily confined to structured domains like fashion and music recommendations.
March to September 2026: The Safety and Guardrail Window
Following the paper’s publication, a six-month window elapsed before Google’s official public communication. Industry analysts suggest this period was utilized to evaluate the framework’s propensity for bias in sensitive domains, develop appropriate guardrails, and prepare the infrastructure for large-scale deployment.
September 15, 2026: Official Google Blog Announcement
Google officially published its research and blog post detailing the R4T Diffusion Model, labeling the system as "production-ready." The public release coincided with anecdotal reports from webmasters and SEO professionals noting unexpected traffic shifts, altered link presentations within AI-driven search modes, and potential unannounced algorithm updates—fueling speculation that the system may already be active in production environments.
Supporting Data and Technical Mechanics
To understand the magnitude of Google’s engineering feat, one must examine the mechanics of traditional AI search bottlenecks and how knowledge distillation resolves them.
The Problem with Autoregressive Fan-Outs
Historically, complex AI search features relied on autoregressive models to generate query expansions sequentially. While these models could yield high-quality results, their computational cost scaled linearly—and often painfully—with the size of the context batch. In heavy production environments, latency could balloon toward 50 seconds per query. For real-world web search, where users expect instantaneous responses, this delay created an unworkable engineering barrier.
The Power of Neural-Network Knowledge Distillation
To bypass this barrier, Google utilized knowledge distillation, a landmark machine learning technique famously pioneered with the assistance of ex-Google executive Jeff Dean in 2015.
- Teacher Training: Researchers first trained an expensive, high-capacity model to exhibit ideal query fan-out behavior, capturing high-quality outputs and complex reasoning paths.
- Student Imitation: They then trained a drastically smaller model—the 53.9M-parameter R4T diffusion model—to mimic the teacher model’s behavior using synthetic data generated via reinforcement learning.
- Parallel Pass Execution: Unlike sequential autoregressive models, the diffusion model generates all target directions simultaneously in a single, non-autoregressive parallel pass within a continuous embedding space.
By distilling complex behavior into a lightweight model, Google successfully "smashed the latency bottleneck," achieving high-fidelity results while using a fraction of the computing power.
Official Responses and Expert Insights
Google’s research team has been transparent about both the immense capabilities and the inherent limitations of the R4T framework. In their official documentation, the researchers emphasized the practical viability of the system for real-world applications:
"From a systems perspective, R4T provides a practical pathway for deploying retrieval models that optimize higher-order properties such as diversity, coverage, and complementarity while maintaining low inference latency," the research paper states. "This is particularly relevant for real-world applications where fan-out retrieval is desirable but autoregressive generation is prohibitively expensive, including recommendation systems, creative search, and exploratory information access."
Furthermore, the team highlighted the broader implications of reinforcement learning in ambiguous or subjective tasks:
"The idea of using RL to synthesize objective-aligned training data may extend beyond retrieval to other structured generation tasks where ground truth is ambiguous or subjective, such as planning, design, and creative generation."
However, the researchers also injected a note of caution regarding safety and ethical oversight. Unlike the promotional tone of the corporate blog post, the academic paper explicitly warns that unchecked diffusion models could amplify biases in sensitive contexts.
"Responsible deployment requires domain-specific bias audits, inclusive design practices, and appropriate oversight mechanisms," the authors wrote at the conclusion of the paper. "We view R4T as a tool for controlled retrieval design that must be accompanied by safeguards rather than a substitute for human judgment and ethical oversight."
Implications for the Tech Industry, Search, and SEO
The deployment of the R4T Diffusion Model carries sweeping implications across multiple sectors, fundamentally altering how search engines, recommendation engines, and digital marketers operate.
1. The Era of Instantaneous AI Search
By dropping query fan-out latency to sub-second thresholds, Google can affordably scale deep, multi-faceted AI search features to billions of users globally. Users can expect more robust, nuanced search results that dynamically explore various angles of a query without experiencing sluggish page load times.
2. Disruption in Recommendation Ecosystems
Beyond traditional search engines, systems like YouTube recommendations and Google Discover rely heavily on complex retrieval pipelines. The R4T framework allows these platforms to surface diverse, highly complementary content recommendations without requiring constant, resource-intensive online optimization.
3. Broadened Applications in Creative and Structured Generation
Because the framework excels at structured generation where ground truth is subjective, developers anticipate seeing similar distillation architectures applied to automated planning, design software, and creative writing assistants.
4. What This Means for SEO and Content Creators
For digital marketers and SEO professionals, the optimization of query fan-outs means Google’s AI is becoming increasingly proficient at understanding user intent and mapping out micro-topics related to broad queries. As search engines diversify their fan-outs to avoid redundant synonyms and capture deeper contextual angles, content creators will find greater rewards in producing comprehensive, highly specialized, and semantically diverse content that directly satisfies distinct sub-queries.
5. Ethical Oversight and Deployment Questions
While the industry weighs the commercial benefits of faster AI search, Google’s internal warnings regarding bias serve as a reminder of the challenges ahead. Whether the company has fully deployed R4T across all sensitive queries or ring-fenced it for safer commercial and informational topics remains an open question. Nonetheless, the framework sets a new technical benchmark for efficiency, proving that massive scale no longer requires massive, unsustainable computational overhead.